Director of Science · Amazon
Building computer vision and generative AI systems — from virtual try-on to shoppable images — that ship to Amazon customers, and coaching the next generation of tech leaders in fast-paced, high-stakes environments.
📍 Berlin, Germany
I lead a cross-functional, centralized AI innovation team at Amazon, spread across several locations in Germany. Our mission: find the highest-impact computer vision and AI problems in the business and ship them as products customers actually use.
Being centralized gives me a mandate most people in my role don't get — we scan Amazon's entire business for the highest-impact problems and assemble the right mix of disciplines to solve them. That means an unusually diverse portfolio: different technologies, domains, and constraints, rather than one narrow lane.
What I care about most is enabling people to do their best work. A decade leading innovation teams has convinced me people are a bigger lever than any technology, so I invest as much in developing them as in the work itself. Watching someone grow into a leader is what keeps me doing this.
AI is changing how we build products and develop people — old playbooks don't work anymore. If you're not constantly reinventing your approach to leadership, you won't thrive. It's not just what we build that's shifting, but how we lead the people building it and get it in front of customers. That shift is what I spend most of my time thinking about now.
10+ years leading CV & AI teams in Germany · 25+ products shipped · Multi-billion dollar customer impact
Generative AI · Computer Vision · Image & Video Understanding and Generation
Developing the next generation of AI leaders in fast-paced, high-stakes environments.
Graz University of Technology, Austria, 2007
Graduated with highest distinction
Graz University of Technology, Austria, 2003
Graduated with highest distinction
One of my deepest passions is developing the next generation of leaders in fast-paced industry environments, helping brilliant scientists and engineers grow not just as technical experts, but as self-aware, resilient, and impactful human beings.
After more than a decade leading science teams at Amazon, I've come to believe that the biggest leverage point in any organisation isn't the technology: it's the people. Coaching and mentoring is not a side activity for me; it's a core part of how I lead. I invest deeply in building the inner toolkit of my team: the resilience to own outcomes, the clarity to cut through noise, and the self-awareness to stay grounded when everything around them is moving fast.
The rise of Generative AI has made this more urgent, not less. The pace of change is relentless, the stakes are high, and the old playbooks don't always apply. What endures is a strong inner foundation: a growth mindset, sound mental models, honest communication, and the courage to build teams where people can do their best work. These are skills that can be learned and trained, and I'm deeply committed to helping people build them.
Intelligence and skills are built, not fixed. I help people embrace discomfort as a signal of growth: to ask the questions they've been afraid to ask, treat failure as data, and stay relentlessly curious in a world where the half-life of knowledge is shrinking fast.
Exceptional leaders refuse the victim mindset. When projects derail, they ask “What can I do right now?” rather than crafting explanations. I coach on reclaiming agency: owning outcomes, not just credit, and choosing usefulness over comfort when it matters most.
Honest, direct communication is a force multiplier. I work with leaders on giving and receiving feedback without flinching, managing up effectively, and influencing without formal authority: the skills that determine whether great ideas actually get implemented.
Great teams are built on psychological safety, not just talent. I help leaders spot and dismantle the subtle dysfunctions, like teams that optimise for appearances over outcomes, and create environments where top performers do the best work of their lives.
Good decisions come from good thinking frameworks. I help leaders build a toolkit of mental models: first-principles reasoning, inversion, systems thinking, so they can cut through noise, know when to persist and when to stop, and reason from fundamentals rather than analogy.
The old playbooks don't fully apply anymore. I share a hands-on perspective on how AI is reshaping leadership: from using it as a judgment-free thought partner and learning environment, to prototyping ideas in minutes, to re-thinking what it means to create impact in AI-native organisations.
Amazon Development Center Germany · Berlin, Germany
Leading a cross-functional Computer Vision & AI innovation organization across multiple German sites. Defining long-term CV & AI strategy with direct reporting to Retail VP. Key production launches include image & video generation, visual recommendations, image translation, shoppable images, image & video moderation, virtual try-on applications, visual copyright infringement detection, video maturity recognition, and accessibility features on Echo Screen Devices.
Amazon Development Center Germany · Berlin, Germany
Grew and led the Applied Science team, fostering research-to-production pipelines for computer vision applications across multiple Amazon product lines.
Amazon Development Center Germany · Berlin, Germany
Founded and built the computer vision science team in Berlin, Germany, establishing the infrastructure and culture for research-driven product innovation at Amazon Berlin.
Institute for Computer Graphics and Vision · Graz University of Technology, Austria
Research on image segmentation, shape matching, and retrieval. Supervision of PhD students and international research collaborations.
Institute for Computer Graphics and Vision · Graz University of Technology, Austria
Led the Virtual Habitat research group. Supervised eight PhD students.
Institute for Computer Graphics and Vision · Graz University of Technology, Austria
Thesis:"Advanced Segmentation and Tracking Algorithms and Their Application to 3D Paper Structure Analysis". Graduated with highest distinction.
Institute for Computer Graphics and Vision · Graz University of Technology, Austria
Thesis: "Object Segmentation in Videos". Graduated with highest distinction.
Awarded by the State Government of Styria (Austria) for outstanding early-career scientific achievement.
Link to Article (German) →International Conference on Pattern Recognition (ICPR), "Using Web Search Engines to Improve Text Recognition"
View award photo →OAGM/AAPR Workshop, "Finding Stable Extremal Region Boundaries"
OAGM/AAPR Workshop, "MSER Templates for 3D Pose Tracking"
Asian Conference on Computer Vision (ACCV): "Detecting Partially Occluded Objects with an Implicit Shape Model Random Field"
Selected posts on leadership, learning, and the age of Generative AI. Published on LinkedIn and Medium.
A candid reflection on imposter syndrome, self-doubt, and the messiness behind a career that looks polished from the outside.
A childhood dream deferred by programming complexity, finally realised with AI. On creativity, persistence, and what it means to build something truly your own.
AI creates the first truly judgment-free learning environment in human history. The only barrier to growth is giving yourself permission to ask.
When projects derail, leaders reveal their true nature. Exceptional ones refuse the victim mindset and ask: what can I do right now?
The same principles that make us effective communicators with humans apply when prompting AI. Mastering one may sharpen the other.
A regular forum where every team member has a voice. How Kaizen Town Halls build psychological safety and turn tensions into rapid, meaningful change.
When teams optimise for how they appear to leadership rather than real outcomes, the facade can look strong right up until it suddenly isn't.
Great decisions don't come from experience alone. They come from building a diverse toolkit of thinking frameworks that cut through noise and bias.
When you can build your own tools in less than a lunch break, you move from passive observer to proactive creator. The only remaining obstacle is curiosity.
Over 50 accepted, peer-reviewed publications spanning computer vision, machine learning, and artificial intelligence.
Full record on Google Scholar.
26 papers accepted at the premier "Big Five" CV venues — among the most selective in all of computer science.
Conference on Computer Vision & Pattern Recognition
Ranked #1 globally among all CS conferences · ~22% acceptance rate · 13,000+ annual submissions
International Conference on Computer Vision
Biennial IEEE flagship of computer vision · ~25% acceptance rate · 8,000+ submissions
European Conference on Computer Vision
Co-flagship with ICCV · ~28% acceptance rate · 8,500+ submissions
Asian Conference on Computer Vision
🏆 Best Paper Award 2012Premier Asian venue · rigorous peer review
British Machine Vision Conference
Leading European specialty venue · h5-index 65 · rigorous peer review
Austrian Workshop on Computer Vision
🏆 2× Best Paper AwardLargest CV conference in Austria · running since 1981 · 43+ editions
International Conference on Pattern Recognition
🏆 Best Paper Award 2008IEEE’s flagship pattern recognition venue · biennial · running since 1973
Highlights from 50+ papers — top-cited works & award winners.
Matches food images to recipes with a hierarchical Transformer trained on Recipe1M.
Cross-modal recipe retrieval — matching food images to recipes and vice versa — is key for intelligent food discovery. This paper introduces a hierarchical recipe Transformer that attentively encodes individual recipe components (titles, ingredients, instructions), paired with a self-supervised loss that leverages semantic relationships within recipes. The approach enables training on both image-recipe and recipe-only samples, achieving state-of-the-art results on the Recipe1M dataset. Code and models released publicly via Amazon’s GitHub.
Learns per-attribute embeddings so changing one visual attribute leaves others unaffected.
Interactive fashion retrieval lets users refine image search by modifying specific visual attributes such as color or sleeve type. Existing methods learn entangled embedding spaces, causing unintended changes when a single attribute is manipulated. This paper trains convolutional networks to learn separate, attribute-specific subspaces so that swapping one attribute leaves others unaffected. The unified model handles attribute manipulation retrieval, conditional similarity retrieval, and outfit complementary item retrieval, achieving state-of-the-art performance across all three tasks.
Cuts segmentation compute 40× by replacing spectral analysis with gradient optimization.
State-of-the-art image segmentation relies on hierarchical structures built from local feature cues analyzed via spectral methods, but both steps remain computational bottlenecks. This paper shows that a discrete-continuous optimization of oriented gradient signals delivers segmentation performance competitive with the state-of-the-art on the BSDS 500 benchmark — without any spectral analysis — reducing computation time by a factor of 40 and memory requirements by a factor of 10.
Recasts image-based localization as classification with random ferns for faster matching.
Image-based localization matches query image interest points to a sparse 3D point cloud to recover camera pose. Standard approaches represent each 3D point by a single descriptor centroid, ignoring the full set of associated 2D descriptors. This paper reformulates matching as a discriminative classification problem using random ferns, which is memory- and runtime-efficient. An extension projects features into fern-specific embedding spaces, improving match rates and outperforming nearest-neighbor baselines.
Unifies prior diffusion-based retrieval methods, hitting 100% on the MPEG-7 benchmark.
Diffusion on affinity graphs propagates similarity information across a manifold to improve retrieval ranking. This paper provides a comprehensive revisit of diffusion-based retrieval, surveys the state-of-the-art, and derives a unified generic framework of which prior methods are special cases. Evaluating the framework across multiple retrieval tasks yields new algorithm variants; one achieves a perfect 100% bullseye score on the widely used MPEG-7 shape retrieval benchmark.
Extends the Implicit Shape Model into a random field that cleanly separates overlapping objects.
This paper extends the Implicit Shape Model for object detection into a probabilistic random field formulation that naturally handles partial occlusion. A sparse graph encodes patch-to-instance voting in a semantically meaningful label space. A novel inference procedure efficiently minimizes the resulting energy without a fixed non-maximum suppression radius, cleanly separating even strongly overlapping object instances.
Uses MSER region templates for real-time, illumination-robust 3D pose tracking.
Closed MSER contours detected on a reference object form stable, perspective-covariant templates. A classifier trained on these regions enables robust, frame-to-frame tracking, with 3D pose recovered via perspective-n-point from matched regions. The approach leverages MSER’s efficiency and robustness to illumination change, enabling real-time pose estimation on textured planar and near-planar targets.
Localizes object categories via partial edge-contour matching, skipping costly pre-processing.
Object category localization is cast as a partial edge-contour matching problem against a single shape prototype, avoiding error-prone pre-processing such as contour decomposition or interest-point detection. All extracted edges participate in a partial contour matching step; matched fragments vote for location hypotheses via generalized Hough-style accumulation. The method yields competitive results on challenging benchmarks including ETHZ shapes and INRIA horses at low computational cost.
Detects perceptually meaningful edges from stable region boundaries, not brightness gradients.
Rather than responding to local brightness discontinuities like Canny-style detectors, this method detects edges by identifying boundaries of maximally stable image regions. A component tree is built by thresholding the image at all levels; nodes at adjacent levels are compared to find region boundaries that remain geometrically consistent across a range of thresholds. The result is a fast, mid-level edge detector that captures perceptually meaningful boundaries.
Merges multiple globally-optimal saliency segmentations into one coherent result.
Affinity propagation clustering on local color and texture models identifies multiple salient image regions. Each salient region seeds a figure/ground segmentation obtained by minimizing a convex weighted total variation energy, guaranteeing a globally optimal binary solution per seed. The resulting redundant segmentations are merged into a single composite by analyzing local certainty across all solutions, producing coherent multi-region outputs without user initialization.
Uses web search co-occurrence statistics to correct noisy MSER-based text recognition.
Initial character recognition via MSER-based text detection yields noisy per-character hypotheses. This paper exploits web search engines at two levels of contextual granularity to re-rank and correct initial outputs: word-level queries filter implausible character sequences, and phrase-level queries leverage web co-occurrence statistics. Even a low-quality base recognizer achieves substantially improved accuracy when augmented with this web-based contextual post-processing.
Speeds up MSER tracking 4–10× by propagating region identities across video frames.
MSERs are powerful local feature detectors but are expensive to recompute from scratch each frame. This paper exploits the component tree underlying MSER detection to propagate and update region identities across video frames, reducing per-MSER computation by a factor of 4–10. A weighted feature vector and backward-tracking pass improve data association and robustness, demonstrated on license plate, face, and paper-fiber tracking with consistent speedups over frame-by-frame redetection.
Side projects & experiments on GitHub
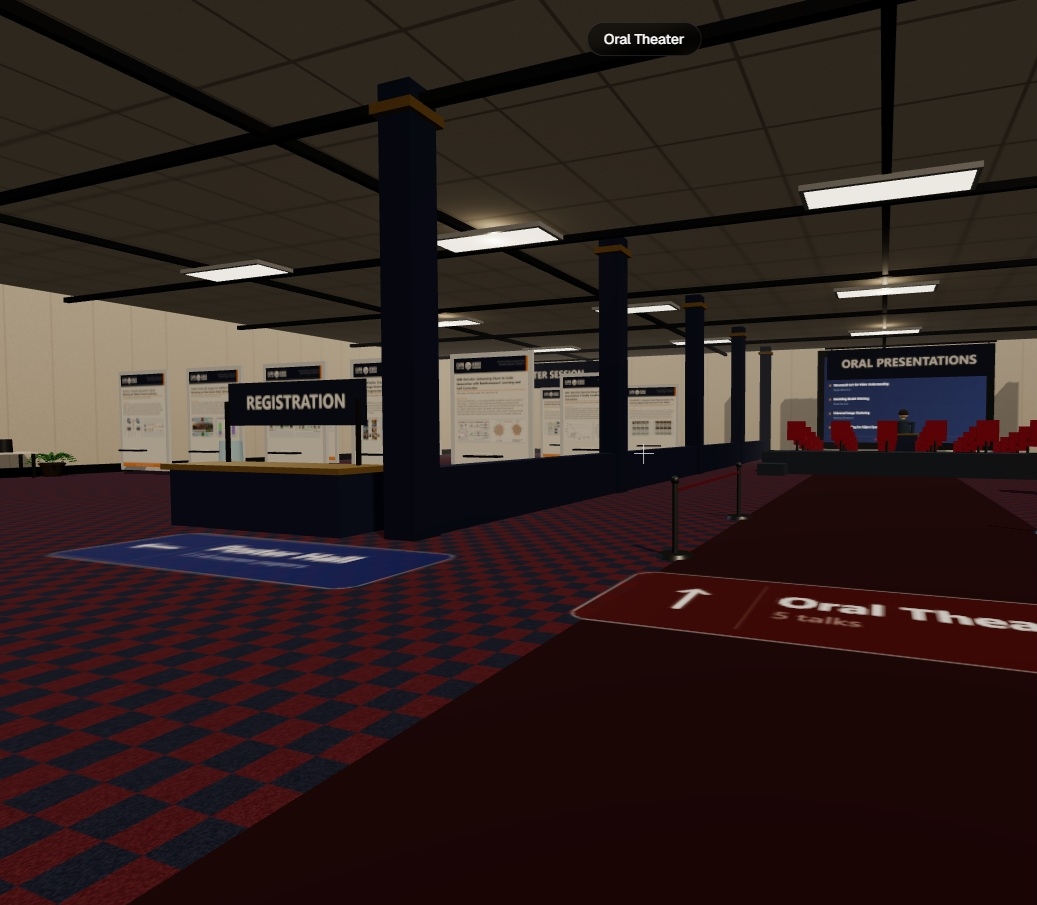
Conference Simulator — step inside an interactive 3D CVPR venue, explore poster sessions, watch oral talks, and visit the industry fair.
FIFA World Cup 2026 betting game — predict match results, compete on a leaderboard, and track your picks across the full tournament.
A text-based adventure game exploring interactive storytelling with AI-generated narratives.
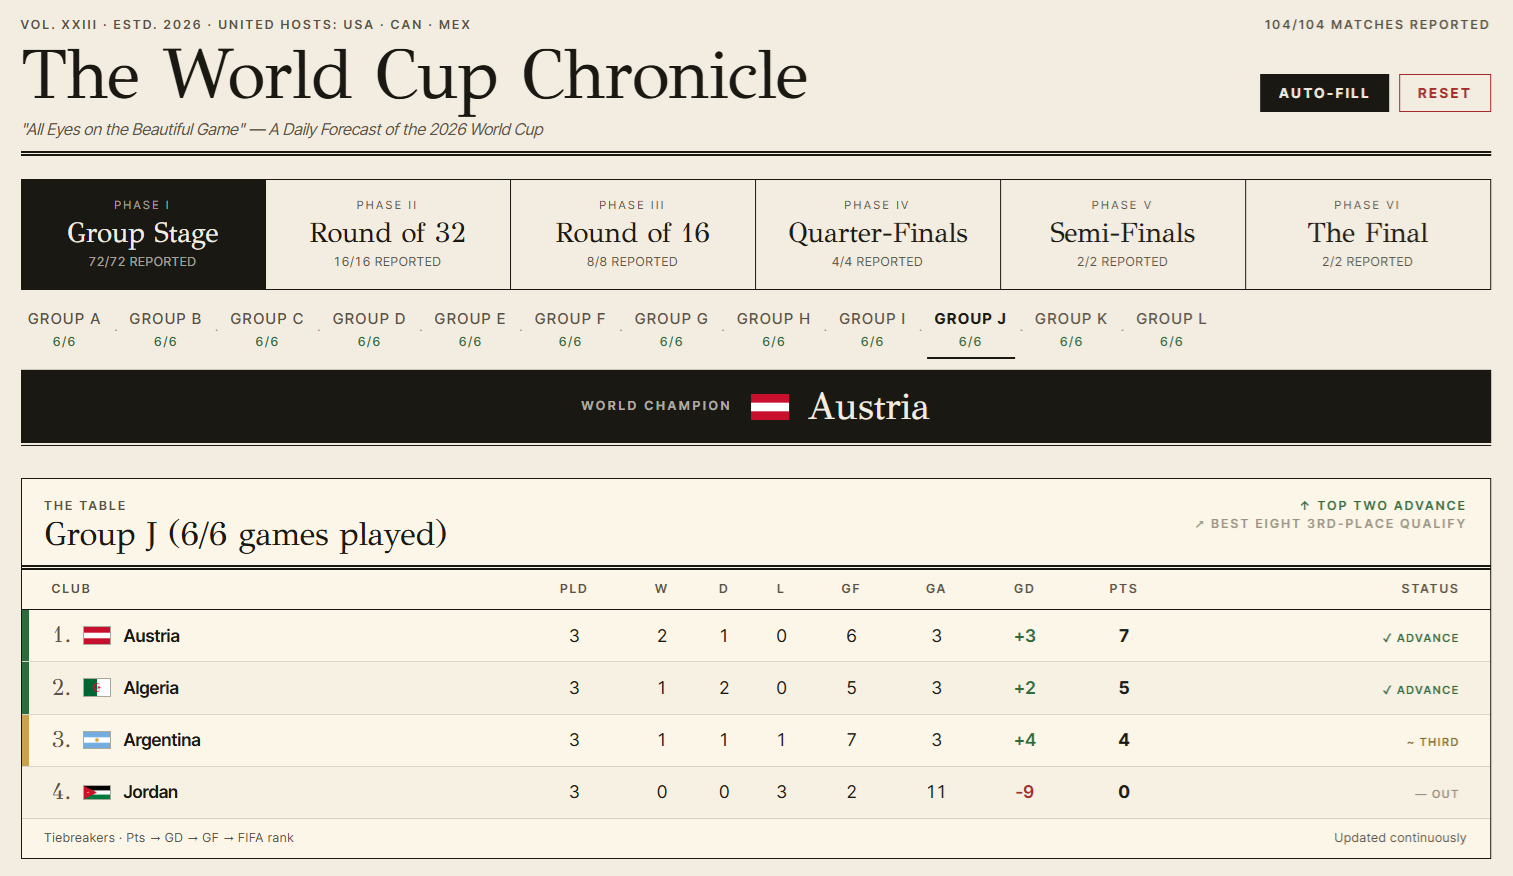
Interactive FIFA World Cup 2026 tournament simulator — enter match results through group stage and knockout rounds to crown a champion.
An exercise tool for learning Japanese.
An interactive soccer story game with branching narratives and match simulation.
An Easter-themed treasure hunt game with snakes and interactive challenges.
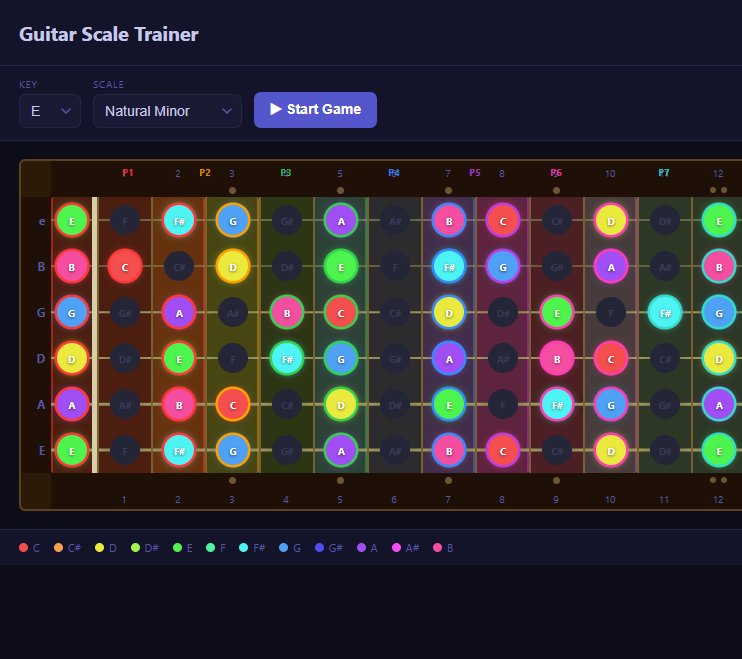
Interactive fretboard trainer for learning guitar scales and modes.
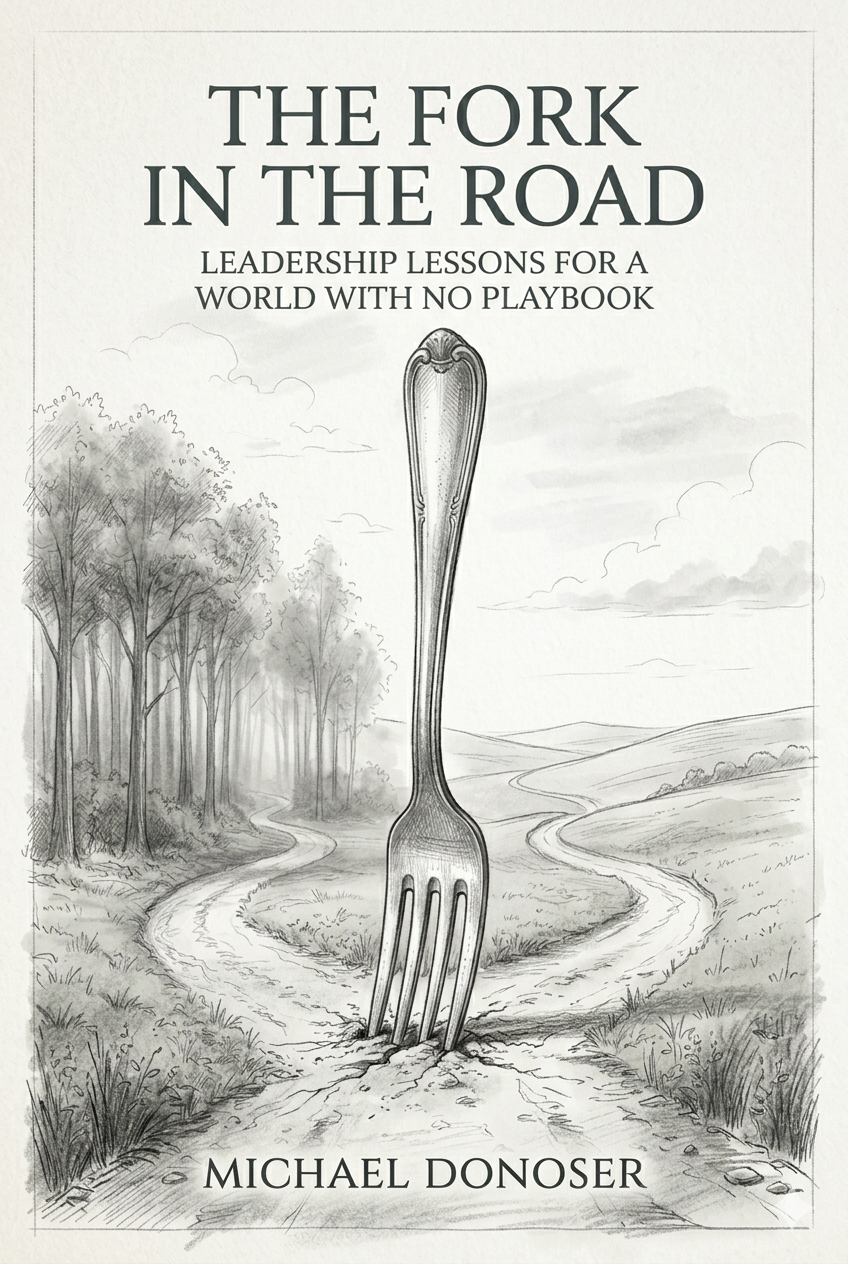
A book in progress — stories from eleven years leading tech teams at Amazon.
Why do some teams seem almost effortlessly effective — energised, honest, resilient under pressure — while others, staffed with equally talented people and similar resources, quietly struggle? This book explores that question through small, human stories drawn from over a decade inside Amazon. Each story follows two hypothetical teams facing the same situation. The difference is never skill or intent — it is the specific, repeatable behaviours that produce results you can actually start using on Monday morning.
The chapters are written for everyone on a team, not just those with the word “manager” in their title. Everyone is a leader. Every person shapes culture.
Explore my work, publications, and professional background across these platforms.
Always happy to hear from fellow researchers, builders, and leaders.